Multilingual SEO
hreflang Without the Headaches: A Field Guide
The five mistakes that quietly split your ranking signals across locales, and how to fix them.
6 min readEverything you need to know
A common question is whether dynamic rendering and cloaking are the same thing. The short answer is no. The longer answer is worth two minutes, because the advice most articles give you on this is three years out of date, including the one that probably sent you here.
Cloaking is showing search engines one thing and people another, on purpose, to game rankings. That’s a spam violation, and Google will deindex you for it.
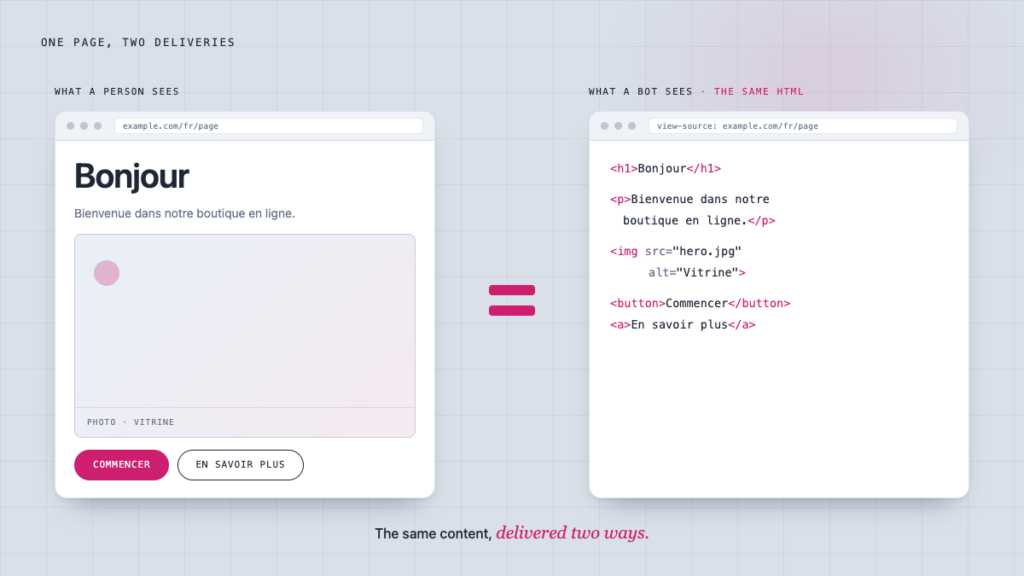
Dynamic rendering and flattening do the opposite. They show the same content to both. They just pre-build it into plain HTML so a crawler can read the page without running JavaScript. Same content, different delivery. That’s the whole distinction, and it’s the line you can’t cross. The version a bot sees and the version a person sees have to match.
So the question isn’t really “is this cloaking.” It’s “am I accidentally serving two different pages.” Most of this article is about staying on the right side of that line, and about one thing that changed in 2024 that the older guides never caught up to.
Google’s spam policy defines cloaking as presenting different content to users than to search engines with the intent to manipulate search rankings. The typical example is a page that shows Google a travel guide and shows visitors an unrelated storefront.
Two things make it cloaking, and you need both. First there’s a content difference: the bot and the human get materially different pages. Second there’s intent: the difference exists to trick the ranking system. A page that serves Googlebot pre-rendered HTML of the exact content a visitor sees doesn’t meet the cloaking criteria. It isn’t deception. It’s a translation from one format to another.
The penalty for getting it wrong is serious and slow to reverse: affected pages get deindexed, and in bad cases the whole site does. That’s why the anxiety is reasonable. It’s also why the fix is precise rather than vague. You don’t avoid cloaking by just being careful, you avoid it by keeping the two versions identical in substance.
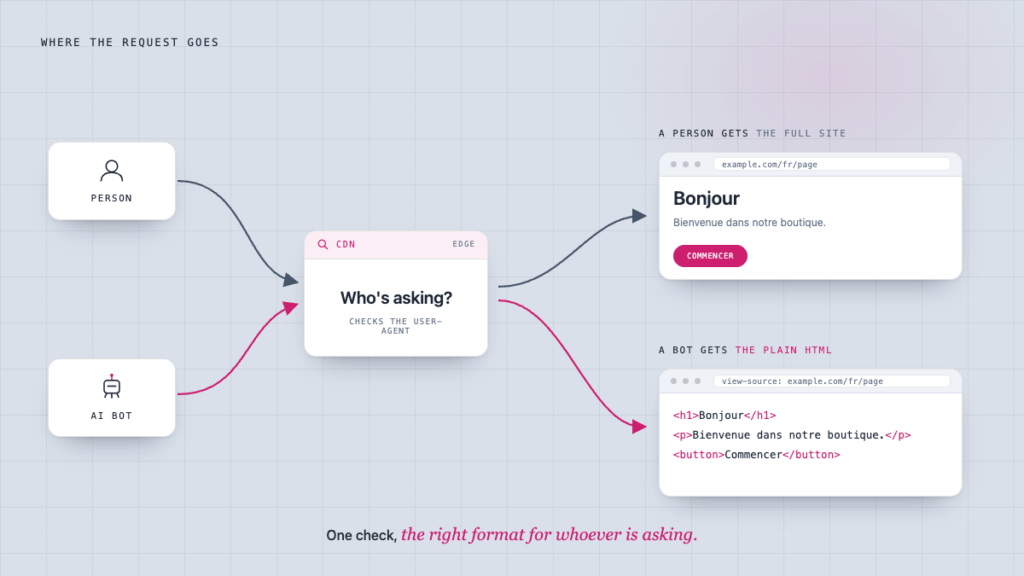
Dynamic rendering is a setup where your server looks at who’s asking. A normal visitor gets your usual JavaScript app. A known crawler gets a pre-rendered HTML snapshot of that same page, built ahead of time so nothing has to execute. The detection happens by user-agent, usually at the CDN or web-server layer, before the request ever reaches your app.
Flattening is the same mechanism applied to a translated site. When Bablic translates your pages, the translated content is injected by JavaScript in the visitor’s browser. That may work for viewers, but it’s a problem for anything that doesn’t run JavaScript because the translated words don’t exist until the script fires. Flattening solves it by serving bots a “flat” HTML version of the page with the translation already baked in: for example, the French page at the French URL, fully rendered, no script required. A human who lands on that flat page and has JavaScript gets redirected straight to the rich experience, so nobody browses the stripped-down version by accident.
The content is the same either way. A bot reading your flattened French page sees the same French content a shopper sees on that same French URL. That’s not two pages. It’s one page, delivered two ways.
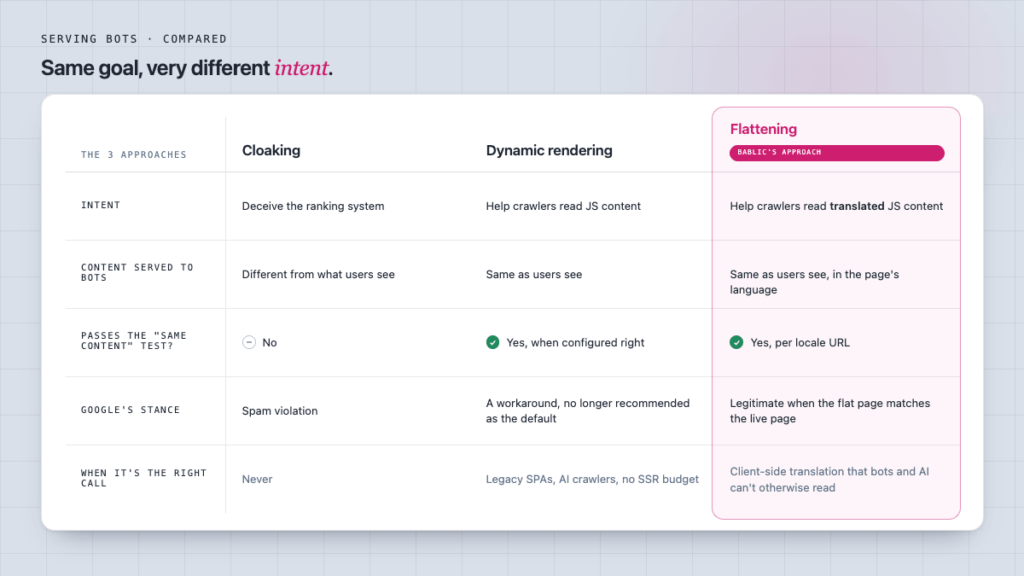
Here’s where most “dynamic rendering vs. cloaking” articles are stuck in the past. They tell you dynamic rendering is “Google-approved” and “white-hat.” That was the framing around 2019, but it isn’t the framing now.
In 2024 Google quietly rewrote its guidance. Dynamic rendering moved from a recommended technique to, in Google’s own words, a workaround and not a long-term solution. The reason is simple: Googlebot runs a current version of Chrome and renders JavaScript on most pages without help. So for Googlebot specifically, bolting on a second rendering pipeline is usually solving a problem you no longer have. A second pipeline is one more thing that can break, go stale, and start serving crawlers something different from what users get which, ironically, is how well-meaning teams drift into accidental cloaking.
We could pretend none of that happened. It’s a strange thing for a company that sells flattening to bring up. But the honest read is more useful: Google rendering JavaScript well is true for Googlebot, and it changes nothing about the two situations where pre-rendered HTML still does real work in 2026.
There are three cases, and none of them are about tricking Google.
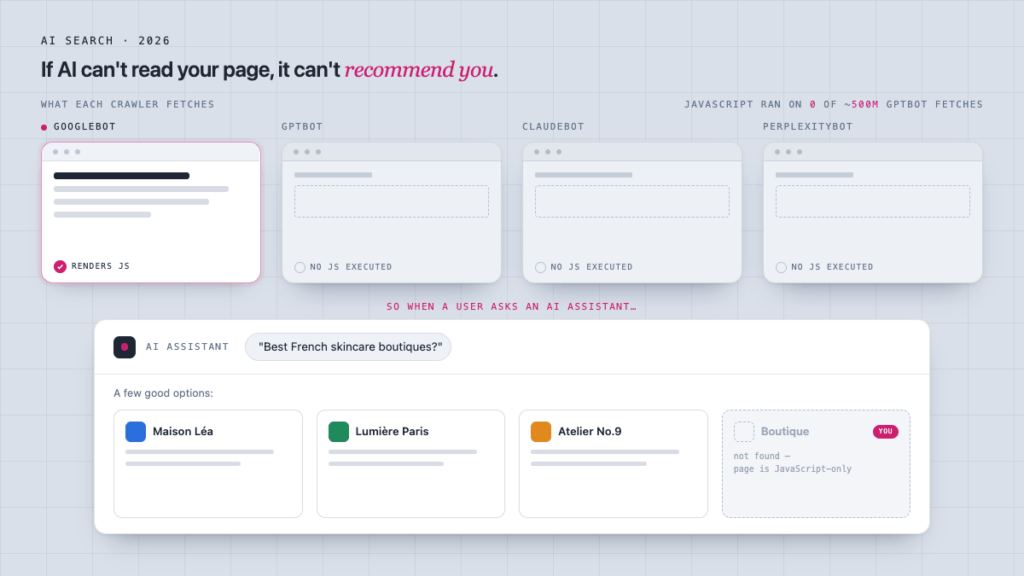
AI crawlers don’t render JavaScript. This is the big one, and it’s newer than most of the articles on this topic. Googlebot renders JS; the AI crawlers don’t. GPTBot, ClaudeBot, PerplexityBot, and the rest fetch your raw HTML and never run a script. If your content only appears after JavaScript runs, like product details, comparison tables, the translated copy on your international pages, it simply isn’t there as far as ChatGPT and Perplexity are concerned. Serving them flat HTML is the difference between being quotable in an AI answer and being absent from it.
Client-side translation layers. If your translations are injected in the browser, as Bablic’s are, the translated DOM doesn’t exist until the script fires. Googlebot can often render it given time, but Googlebot crawls from the US and doesn’t send an Accept-Language header by default, so a single-URL site that switches language by browser setting can get crawled entirely in its default language. Separate locale URLs with hreflang are the reliable fix, and flattening is what puts real, indexable translated HTML at each of those URLs. The full breakdown is in our multilingual SEO best practices guide.
Legacy SPAs with no SSR budget. If you’re sitting on a large JavaScript app you can’t re-architect this quarter, dynamic rendering is still a legitimate holding pattern. Google calls it a workaround, not something to be avoided at all costs. A workaround that keeps you indexed while you plan an SSR migration is a reasonable thing to run.
If none of these three describe you and you can server-render your content directly, do that. It’s the cleaner answer and you won’t need a second pipeline at all. We’d rather tell you that than sell you something you don’t need.
This is the question the whole category steps around, and the answer is straightforward: no, as long as each language lives at its own URL and the bot gets that URL’s language.
Cloaking is a same-URL problem. It’s when example.com/page shows the crawler one thing and the visitor another. Translation done properly isn’t same-URL. For instance, example.com/fr/page is the French page, and everyone who requests it, bot or human, should get French. When a bot asks for the French URL and flattening hands back French HTML that matches what a French-speaking visitor sees there, the content is identical. The “same content” test is satisfied per locale, which is exactly how Google expects multilingual sites to work.
Serving a translated page could become cloaking if you serve a bot a different language than the URL implies, or if you stuff the flat version with extra keywords or links the live page doesn’t have. The rule is the same as everywhere else on this page: match the live page. Translation is allowed to change the words but it isn’t allowed to change the substance.
You almost never get a cloaking penalty on purpose. You get it because the two versions drifted apart. Here are the usual culprits:
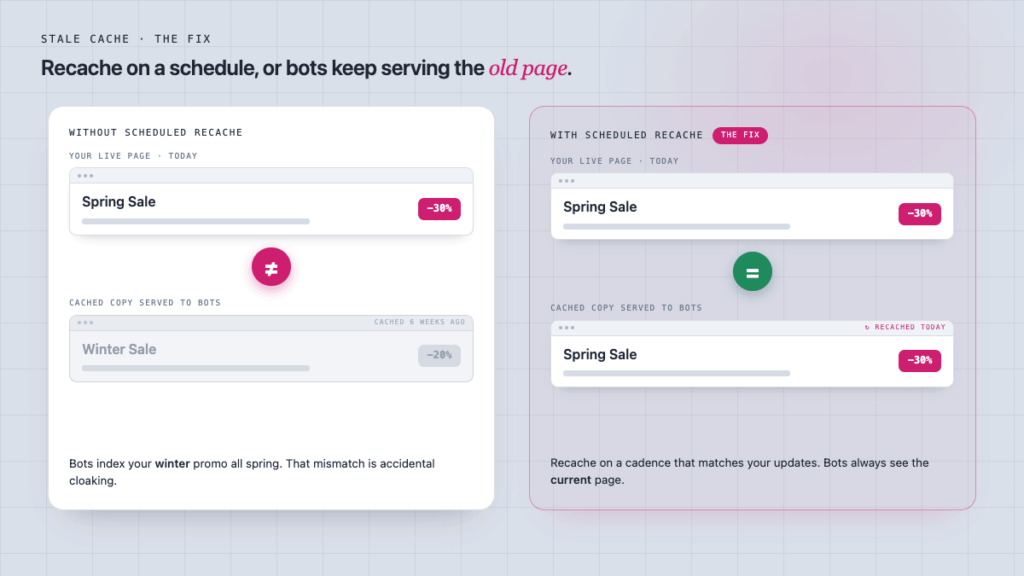
Stale cache. This is the most common one in practice, and the one Reddit threads complain about most. A pre-rendering service caches the HTML it built and keeps serving it. You update the live page. Until the cache refreshes, bots see the old version and users see the new one: a classic content mismatch. Set a recache cadence that matches how often your pages actually change.
Partial renders. If the snapshot times out or a resource fails to load, the flat page can be missing chunks of content, meaning the bot’s version is genuinely thinner than the human’s. Watch your render stats for pages that come back suspiciously small or slow.
Dynamic rendering still earns its keep in browser-based translation. Flattening ahead of time ensures pages are fully translated before indexing and lets you review the output before it goes live so you’re not left hoping Google rendered everything correctly.
“For SEO” content. The temptation to add keyword copy, extra links, or a tidier layout to the bot version only. Don’t. The moment the flat page says something the live page doesn’t, you’ve built the thing you were trying to avoid.
Wrong locale. The translation-specific failure: a misconfigured rule serves the bot a different language than the URL represents, or falls back to the default language when it can’t resolve one. The flat page has to match the live page in the right language, not just in general.
You don’t have to take this on faith. You can check it, and you should check it regularly, not just once at launch.
Open Google Search Console and run the URL Inspection tool’s live test on a few representative pages. Compare what Google renders against what you see in a browser at the same URL. They should say the same thing. Spot-check a translated URL the same way and confirm the language matches. If you’re on a flattening setup, most services, Bablic included, let you view the flat version directly with a debug flag, so you can read exactly what bots are getting and diff it against the live page yourself. Then watch your render and recache stats for timeouts and undersized pages, because those are partial renders waiting to become mismatches.
The whole audit is one question asked from a few angles: does the bot see the same page I do? If yes, you’re not cloaking, regardless of how the HTML got built.
Flattening is the right tool when your translated content is assembled in the browser and you need bots and AI crawlers to read it anyway. That’s a real and common situation, especially if translation was added to a site that wasn’t built for it. Bablic’s Pre-Rendering Flattening handles the bot detection and the per-locale HTML at the CDN layer, so the translated version of each page is there for crawlers without you re-architecting the site. And if you want to understand how the translation layer itself works, our Machine Translation Guide 2026 breaks down how the translation layer fits into the broader pipeline.
It is not the right tool if you can render your translated content on the server in the first place. If you’re on a framework that server-renders by default and your translation pipeline can run there too, then that is the better option. You’ll have one version of every page and nothing to keep in sync. Flattening earns its place precisely when that option isn’t on the table. If it is, then take it, and skip the second pipeline. That’s the honest call, and it’s the same call we’d make for our own site.
Will I get penalized for using dynamic rendering or flattening?br>Not for using them. You get penalized for serving bots different content than people, which is a configuration mistake, not an inherent property of the technique. Keep the flat version matched to the live version and you won’t get penalized. If you translate your website with Bablic, that’s handled automatically. Bablic detects when pages have been updated and stales the flat version so it gets rebuilt fresh.
Is prerendering the same as cloaking?br>No. Prerendering builds an HTML version of the same page so crawlers can read it without running JavaScript. Cloaking serves different content to deceive. It’s the same mechanism of “detect the bot, serve HTML” but with opposite intent and opposite content.
Do I still need this if Googlebot renders JavaScript now?br>For Googlebot alone, usually not. That’s why Google downgraded dynamic rendering to a workaround. But Googlebot isn’t the only crawler that matters. Bing, Yandex, Baidu, and others don’t render JavaScript and need raw HTML. You also still need it if your translated content is injected client-side and isn’t reliably getting indexed, or if you’re on a legacy SPA you can’t server-render yet.
Does this help with ChatGPT and Perplexity?br>Yes, and this is the part that’s changed. Those crawlers read raw HTML and don’t execute scripts. If your content only appears after JavaScript runs, serving them flat HTML is how it becomes visible to AI answers at all.
Is serving a translated page to a bot cloaking?br>No, when each language has its own URL and the bot gets that URL’s language. Cloaking is a same-URL deception. A French URL returning French content to everyone – bot or human – is just a correctly built multilingual page.
How do I check I’m not accidentally cloaking?br>Run the URL Inspection live test in Search Console and compare it to your live page, language included. View your flat pages directly with a debug flag and diff them against the real ones. Keep an eye on recache timing and render stats so the two versions never drift.
If you’re not sure whether your translated pages are reaching crawlers and AI bots the way they should, a Bablic specialist can walk you through your setup and tell you honestly whether flattening is the right call for your situation. Connect with a specialist
Paste one line of JavaScript and watch your own site translate in minutes. No credit card required.